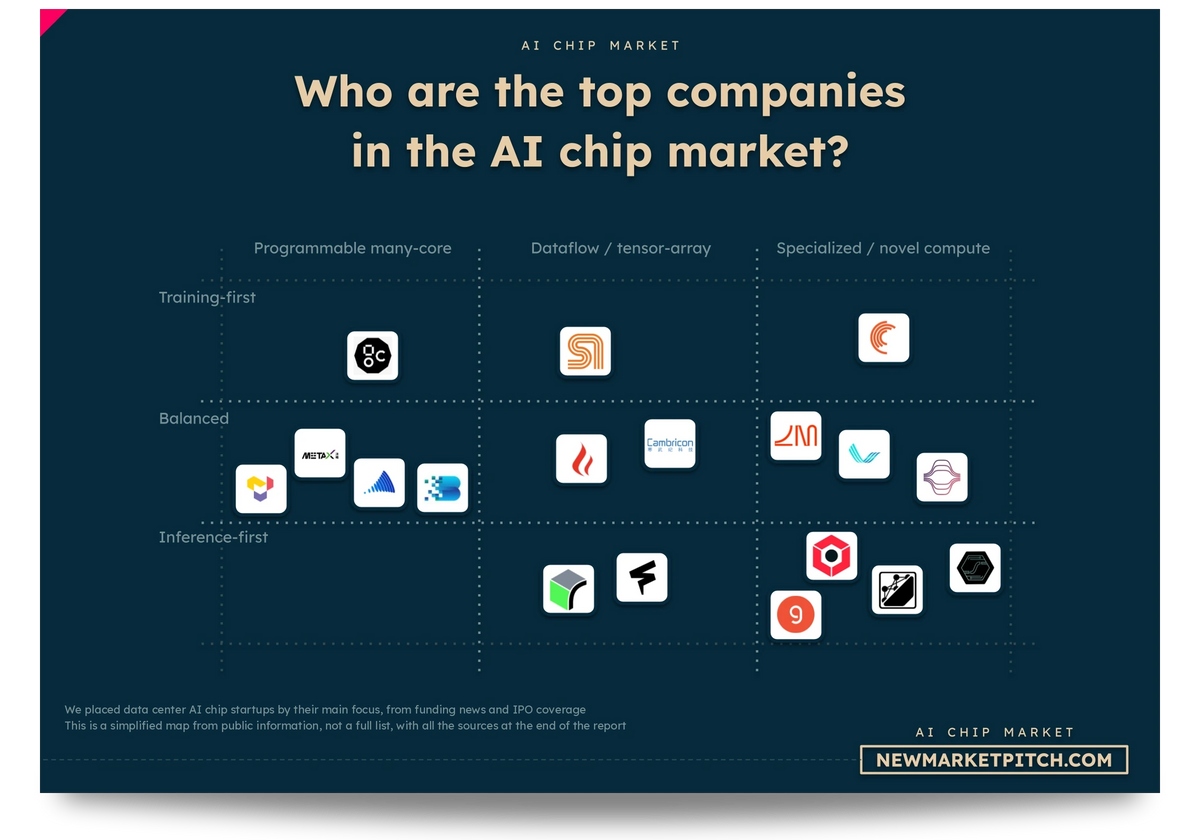
Do you still need Nvidia GPUs for AI inference?


Every funding round, every investor, and who is really ahead in AI chips, in one document. Have a look ↓
Summary
No. You no longer need Nvidia GPUs for AI inference, even to run some of the world's most advanced AI models. Google, Amazon, Meta, AMD, and specialized providers have already proved that large-scale commercial inference can operate on alternative hardware.
The shift is happening in production, not just in laboratories. Anthropic uses more than one million Amazon Trainium2 chips for Claude training and inference, Google serves Gemini using TPUs, and Meta operates hundreds of thousands of proprietary MTIA accelerators. With custom chips now serving real traffic, we look at which technologies are gaining traction in our AI chips report.
Nvidia is not showing signs of an overall business collapse. Its quarterly data-center revenue reached $89 billion, growing 117% year over year, even as competing inference processors gained commercial adoption. Losing some workloads does not necessarily mean losing revenue when the entire AI computing market is expanding rapidly.
The biggest competitive threat comes from repetitive inference workloads. Training a frontier model requires enormous flexibility, but serving the same model billions of times creates opportunities to optimize specialized chips around predictable calculations, memory requirements, and latency targets.
Google and Amazon have an advantage that ordinary enterprises cannot easily reproduce: they control much of the hardware, software, networking, and cloud infrastructure together. Their custom chips can be economically attractive without being universally better than Nvidia GPUs.
Speed is becoming a separate competitive battleground. OpenAI's Cerebras-powered GPT-5.6 Sol Ultrafast demonstrated up to 750 output tokens per second, reportedly as much as 14 times faster than standard processing. That makes specialized hardware particularly interesting for interactive applications, although higher speed does not automatically mean lower cost.
Nvidia's CUDA ecosystem remains a serious competitive advantage. Alternative processors increasingly support familiar tools such as PyTorch and vLLM, but getting a model to run is easier than keeping it fast, reliable, and economical across frequent software updates.
The economics are more complicated than chip prices suggest. A cheaper processor can cost more per generated token if utilization or throughput is lower. Companies need to compare complete serving costs under identical model, quality, volume, and latency requirements.
The next competitive frontier may involve mixing processor architectures within the same inference system. Projects combining Trainium for prompt processing and Cerebras for token generation suggest that different chips could eventually handle different stages of a single AI request.
Nvidia's strongest position is increasingly in flexibility rather than indispensability. Businesses frequently switching models may still find Nvidia the simplest choice, while companies serving stable workloads at enormous scale have growing incentives to develop or adopt specialized alternatives.
Our conclusion is that Nvidia will remain a major AI infrastructure supplier, but inference is becoming a multi-architecture market. The evidence proves that substitution is already occurring; what public financial disclosures cannot establish is exactly how much inference market share Nvidia has lost or whether competitors consistently deliver lower total costs.

Written by the New Market Pitch teamWe track new markets so founders and investors can move faster. About us
Do you still need Nvidia GPUs to run AI models today?
No, you no longer need Nvidia GPUs for AI inference, even for some of the world's most advanced AI models. But Nvidia remains one of the easiest choices for companies that need powerful, flexible, and reliable computing infrastructure.
Google runs Gemini on its own Tensor Processing Units (TPUs). Anthropic uses Google's TPUs and Amazon's Trainium processors to train and serve Claude. Meta has deployed hundreds of thousands of its proprietary MTIA chips across Facebook and Instagram. OpenAI has also introduced an inference service powered by Cerebras. Labs spreading work across several chips makes the leaderboard harder to read, and we untangle who is ahead in our report on who's ahead in AI chips.
These are real commercial deployments. The question has moved beyond whether other processors can run AI models.
Inference is what happens when a trained AI model generates an answer, recognizes an image, recommends a video, or completes a coding task. Every request consumes computing resources. For a popular service handling millions of requests, even a small reduction in computing costs can save a substantial amount of money.
Nvidia's advantage is that its GPUs work across many different models and applications, supported by a mature software ecosystem. Specialized processors can perform better on certain workloads, but they often come with more restrictions.
Why are AI companies trying to replace Nvidia GPUs?
AI companies are developing alternatives to Nvidia because inference costs keep accumulating every time customers use their products. For businesses serving AI models at enormous scale, buying expensive Nvidia infrastructure for every workload is becoming harder to justify.
Google introduced its seventh-generation Ironwood TPU in April 2025, specifically targeting inference-heavy AI workloads. Amazon has expanded Trainium into a major platform for running Claude. Meta has developed multiple generations of processors optimized for recommendations, advertising, and increasingly generative AI.
These companies have different businesses, but they share one important characteristic: they operate enough AI infrastructure to make small efficiency improvements worth billions of dollars over time.
The economics are also changing as AI models become more useful. Training a model is a large development expense, while serving it creates ongoing costs that grow with usage. A company might train a major model periodically, but it could generate billions of responses before the next version arrives.
Has Nvidia already started losing the AI inference market?
Nvidia is facing much stronger inference competition, but there is no convincing evidence that its overall AI infrastructure business is shrinking. Its latest reported financial results show the opposite.
In its second fiscal quarter of 2027, Nvidia generated $89 billion in data-center revenue, compared with approximately $41.1 billion a year earlier. That represents 117% growth and roughly $47.9 billion in additional quarterly revenue. Total revenue reached $96.2 billion, while gross margin stood at 75%.
For perspective, Nvidia added more data-center revenue in one year than many semiconductor companies generate in several years. This happened while Google, Amazon, AMD, Meta, and specialized inference providers were expanding their competing products.
However, we cannot turn those financial results into an exact inference market-share figure. Nvidia reports data-center revenue across multiple products and workloads without separately disclosing how much comes specifically from inference rather than training.
Two things can be true at once. Nvidia's overall AI computing business is growing exceptionally fast, and alternative inference hardware is gaining commercial adoption. Whether Nvidia is losing inference market share, and by how much, remains difficult to measure using public financial disclosures.


This is just a preview page. Don’t worry if a number looks old: the report gets refreshed, and you’ll always get the latest version.
Is Google proving that Nvidia GPUs are no longer necessary?
Google has already proved that frontier AI inference can work at enormous scale without Nvidia GPUs. Its TPU infrastructure supports Gemini and other Google services, while Anthropic has committed to using substantial additional TPU capacity for Claude.
Google's investment in proprietary AI chips goes back more than a decade. Its first TPU was introduced publicly in 2016, and the company has since developed several generations of hardware alongside its own networking and software infrastructure.
The recent expansion is particularly significant. Google announced Ironwood in April 2025 and made it generally available later that year. In October 2025, Anthropic announced plans to access up to one million Google TPUs, representing more than one gigawatt of computing capacity. An April 2026 agreement involving Google and Broadcom added multiple gigawatts of planned next-generation TPU capacity starting in 2027. Plans for up to a million TPUs stay a promise until chips ship; we separate who leads on shipments from who only promises in our AI chips market report.
Google's chips already run production services, and external customers are committing to future generations. The technology has moved well beyond an internal experiment.
The catch is that Google controls the entire system, including hardware, software, networking, and data-center operations. Most businesses cannot reproduce that level of integration themselves.
For customers willing to use Google Cloud, TPUs are now a serious alternative. For companies that want to operate across different clouds or frequently switch between model architectures, Nvidia still offers greater flexibility.
Can Amazon Trainium really replace Nvidia for Claude?
Amazon Trainium has become a serious replacement for Nvidia in Anthropic's Claude infrastructure, with more than one million Trainium2 chips already being used to train and serve the model.
Anthropic disclosed that deployment in April 2026, when it expanded its agreement with Amazon. The partnership included commitments to spend more than $100 billion on AWS technology over ten years and secure up to five gigawatts of additional computing capacity.
That is a huge infrastructure commitment, although we need to distinguish the hardware already operating from future capacity. The million-plus Trainium2 chips were described as being in use. The five-gigawatt agreement covers capacity expected to arrive over time.
Now consider Anthropic's Amazon and Google agreements together. The company is already using more than one million Trainium2 processors and has announced access to as many as one million Google TPUs, alongside additional multi-gigawatt expansions.
These commitments are not directly additive measures of deployed hardware. They cover different systems, delivery schedules, and infrastructure arrangements. But they show that one of the leading frontier-model companies is building its future around several computing architectures.
That would have been a much less convincing strategy when CUDA-based GPUs were virtually the default for demanding AI workloads.

Are Google, Amazon, Microsoft, and Meta all building their own AI chips?
Yes, custom inference chips have become a major strategy for large technology companies, although Google, Amazon, Microsoft, and Meta are at very different stages of deployment.
Meta offers one of the clearest examples. In March 2026, the company disclosed that hundreds of thousands of MTIA processors were already operating in production. These chips handle recommendations and advertising workloads, where huge numbers of similar predictions must be generated continuously.
Meta also announced four newer generations, MTIA 300, 400, 450, and 500, extending its hardware into more demanding generative AI applications. Its April 2026 agreement with Broadcom covered more than one gigawatt in the first phase of a larger custom-chip rollout.
Microsoft is taking a similar approach with Maia. Its newer Maia 300 architecture focuses on memory bandwidth and more efficient token generation, with broader deployments planned from 2027. The company has discussed a target of roughly 40% more tokens per megawatt compared with current GPU-based systems, although large-scale operational savings still need to be demonstrated.
The important difference is maturity. Meta can point to hundreds of thousands of deployed chips, Amazon has more than one million Trainium2 chips serving and training Claude, and Google has years of operating experience with TPUs. Microsoft's next Maia generation still faces a bigger production rollout.
| Company | Proprietary AI chip | What it currently proves | Main limitation |
|---|---|---|---|
| TPU Ironwood | Frontier AI inference and large-scale cloud serving | Closely tied to Google's infrastructure | |
| Amazon | Trainium2 / Trainium3 | More than 1M Trainium2 chips used for Claude training and inference | AWS-specific ecosystem |
| Meta | MTIA | Hundreds of thousands of chips in production | Primarily internal workloads |
| Microsoft | Maia | Custom inference strategy with new deployments planned | Newest generation awaits broad deployment |
| Apple | Apple Silicon / Neural Engine | Local inference on consumer devices | Limited by device memory and model size |
| Cerebras | Wafer-Scale Engine | Ultra-fast frontier-model inference | Specialized infrastructure and limited availability |
| Groq | Language Processing Unit | Commercial low-latency inference | Smaller deployment ecosystem |
| Nvidia | Blackwell / Rubin | Broad AI workloads and large commercial cloud deployments | Cost and dependence on Nvidia's platform |
Can AMD GPUs compete with Nvidia for AI inference?
AMD is now a credible competitor to Nvidia for many AI inference workloads, especially when businesses want to run open-weight models without relying entirely on CUDA.
AMD's Instinct MI350 accelerators support substantial AI models, while its ROCm software platform works with widely used tools such as PyTorch and vLLM. This makes it possible to deploy many inference applications without rewriting the entire system around Nvidia hardware.
AMD has also invested heavily in making its software easier to use. Improvements to ROCm, inference libraries, and model-serving tools address problems that historically discouraged developers from choosing AMD. Software that makes AMD chips easier to adopt is a technology shift, and we follow which technologies are gaining traction in our AI chips market report.
But hardware benchmarks still need careful interpretation. A processor that looks faster on a particular model may perform worse with different batch sizes, context lengths, or precision settings. The efficiency of the software matters almost as much as the theoretical capability of the chip.
We have enough evidence to say AMD can run commercially important inference workloads. We do not yet have enough comparable production data to conclude that AMD consistently delivers lower total costs than Nvidia across different model families.
For enterprises that already support AMD infrastructure, testing Instinct accelerators is increasingly reasonable. Companies that prioritize compatibility with new model architectures may still prefer Nvidia.

This is a preview page. Spotted an outdated number? That’s normal here. The report you get is always the freshest version.
Can Cerebras or Groq run AI inference faster than Nvidia?
Cerebras has demonstrated that specialized inference hardware can make frontier AI models dramatically faster than standard GPU-based serving, while Groq's technology has become important enough for Nvidia to license it.
In August 2026, OpenAI introduced a limited preview of GPT-5.6 Sol Ultrafast, powered by Cerebras. According to OpenAI's announcement, the service generates up to 750 output tokens per second, reaching as much as 14 times the speed of standard processing.
The comparison is unusually useful because Cerebras said the faster service uses the same model architecture, weights, precision, context configuration, and reasoning settings. The improvement therefore comes from how the model is served rather than from substituting a smaller model.
OpenAI's earlier GPT-5.3-Codex-Spark collaboration with Cerebras also demonstrated more than 1,000 tokens per second in a research-preview environment. Different models and serving conditions prevent a direct speed ranking, but both deployments show how much faster token generation can become with specialized hardware.
Groq approached the problem with its Language Processing Unit, designed for predictable, low-latency execution. In December 2025, Nvidia signed a non-exclusive licensing agreement for Groq's inference technology, with founder Jonathan Ross and other engineers joining Nvidia.
Nvidia clearly sees value in specialized inference technology beyond improvements to its conventional GPU designs. It would be strange to license that technology otherwise.
Cerebras and Groq have helped demonstrate that GPUs are not always the fastest way to serve an AI model. But speed alone doesn't tell us which platform is cheapest. A system generating tokens extremely quickly may cost more per request, especially when demand is low or the service requires expensive dedicated capacity.
Do large AI models still need Nvidia GPUs?
Large AI models need powerful processors and substantial memory, but Nvidia GPUs are only one way to provide those resources. Google TPUs, Amazon Trainium, AMD Instinct, and Cerebras systems already support demanding AI workloads.
The memory requirements help explain why large-model inference remains expensive. A dense model with 70 billion parameters needs approximately 140 GB just to store its weights at 16-bit precision. Reducing precision to 8 bits lowers that figure to around 70 GB, while 4-bit quantization brings it to roughly 35 GB.
Those calculations exclude the additional memory needed for context, execution buffers, and other serving operations.
Quantization can therefore make a major difference to hardware requirements. A model that previously needed several accelerators may fit onto fewer devices, although the impact on quality and performance must be tested.
Frontier models introduce another challenge: serving many users simultaneously. A processor may have enough memory to run a model for one user while struggling to deliver acceptable response times when thousands of requests arrive together.
This is where system design becomes important. Memory bandwidth, interconnects, batching, and software optimization determine how much useful work the hardware can deliver.
Nvidia continues to perform well because it combines powerful accelerators with fast memory, networking, and mature serving software. Competitors increasingly provide their own answers to the same technical problems.

Preview only. Some numbers may have changed since we made this page, but your report will be up to date.
Can AI inference run on a laptop or smartphone instead of Nvidia GPUs?
Yes, smaller AI models can now run directly on laptops and smartphones, making Nvidia data-center GPUs unnecessary for a growing range of everyday applications.
Apple's Foundation Models framework is a particularly useful example. In 2025, Apple made an approximately 3-billion-parameter on-device language model available to developers through its software ecosystem. In June 2026, Apple introduced its third generation of foundation models, including updated on-device systems developed in collaboration with Google.
The size difference explains why this works. A 3-billion-parameter model needs around 6 GB for weights at 16-bit precision, but approximately 1.5 GB at 4-bit precision, excluding execution overhead. Efficient quantization and memory management help make local inference practical on supported consumer devices.
Apple's approach allows applications to perform tasks such as summarization, structured generation, and language processing locally. That can reduce network delays and avoid sending certain information to remote servers.
Recent progress also extends beyond compact models. Meta and Apple collaborated in October 2026 to optimize Meta's 816-billion-parameter Muse Spark Open model for high-end Mac Studio hardware using Apple's MLX software framework. This requires a much more capable machine than a typical smartphone, but it shows how far non-Nvidia inference is progressing even with very large models.
Local hardware still has practical limits. Frontier reasoning models, long contexts, and high-volume commercial services can demand far more memory and computing capacity than ordinary devices provide.
For routine tasks, however, the idea that AI must run on a high-end Nvidia GPU is already outdated.
Is Nvidia's CUDA software still keeping customers from switching?
CUDA remains one of Nvidia's strongest advantages because developers can run a wide range of AI models on Nvidia hardware with relatively little extra work.
Nvidia has spent years building software around its GPUs. CUDA provides the underlying programming environment, while tools such as TensorRT-LLM help optimize inference and frameworks such as PyTorch and vLLM support widely used deployment workflows. Software lock-in is a real hurdle for anyone leaving Nvidia, the kind of thing we cover under the biggest unsolved problems in our AI chips report.
Switching processors can create problems that are not immediately visible in a hardware specification sheet. A model might work correctly on an alternative chip but lack optimized support for a particular attention mechanism, quantization method, or distributed execution setup.
AMD's ROCm has become much more capable, and Google and Amazon have also invested in making their hardware accessible through common AI frameworks. Meta is building MTIA support around familiar industry tools, including PyTorch, Triton, and vLLM.
These improvements are gradually reducing the cost of moving beyond Nvidia.
Still, getting a model to run is the easy part. Keeping it efficient in production is harder. Companies need predictable latency, debugging tools, monitoring, and support for frequent updates.
A business serving one stable model may find that optimizing for specialized hardware pays off quickly. A team experimenting with new models every week will often find Nvidia easier to manage. CUDA gives Nvidia a real advantage in that second scenario, and hardware specifications alone won't erase it.

This is just a preview page. Don’t worry if a number looks old: the report gets refreshed, and you’ll always get the latest version.
Are Nvidia GPUs actually more expensive for AI inference?
Nvidia can be more expensive than specialized inference hardware, but the size of the difference depends heavily on the model, workload, and provider. There is no reliable universal percentage by which Nvidia costs more.
The key metric is cost per useful unit of output at the required response speed. Hourly chip prices alone can be misleading.
Imagine one accelerator costs $10 per hour and generates 100,000 output tokens during that hour. Its direct accelerator cost is $0.10 per thousand tokens. A competing processor costs only $6 per hour but generates 40,000 tokens, producing a cost of $0.15 per thousand tokens.
In this hypothetical example, the cheaper machine costs 50% more per output token.
Production workloads add further complications. A fast accelerator sitting idle for much of the day can be less economical than a slower machine used consistently. Networking, input processing, memory, electricity, maintenance, and engineering time also affect the final bill.
Microsoft's Maia efficiency targets, Google's TPU investments, and Amazon's Trainium deployments suggest that large cloud operators expect meaningful savings from hardware designed around their own workloads. However, those expectations cannot be converted into a universal comparison with Nvidia.
We would need independently tested costs for the same model, accuracy level, request volume, and latency target across competing platforms.
For now, Nvidia's premium is easiest to justify when customers value flexibility and software compatibility. Specialized hardware becomes especially attractive when the workload is predictable enough to optimize.
Could splitting AI inference between different chips make Nvidia less important?
Running different stages of AI inference on separate processors could reduce the need for Nvidia GPUs in workloads where specialized hardware performs better. Companies are already developing systems around this approach, known as disaggregated inference.
Large language models generally process requests in two stages. Prefill handles the incoming prompt and builds the model's working context. Decode then generates the response token by token.
These stages put different demands on hardware. Prefill can require substantial computation, especially for long prompts. Decode can be heavily constrained by memory bandwidth and the movement of model weights.
In June 2026, Cerebras announced a collaboration with Amazon that would use Trainium3 for prefill and Cerebras processors for decoding. The companies aimed to combine the strengths of two architectures rather than forcing both stages onto the same hardware.
Cerebras also announced work with AMD on disaggregated inference. Nvidia itself has developed Dynamo, a serving system designed to manage workloads across different resources and improve inference efficiency.
Some of these deployments remain planned rather than fully operational. But the direction is interesting: instead of asking which single processor is best for inference, companies are starting to ask which processor is best for each operation.
That could create significant opportunities for specialized hardware, even if Nvidia continues supplying other parts of the same inference systems.

Do AI benchmarks prove Nvidia is still the best chip for inference?
AI benchmarks show that Nvidia remains highly competitive, but there is no single independent test proving it is the cheapest or fastest option for every inference workload.
MLCommons' MLPerf Inference benchmarks are among the most useful public comparisons because they use defined models, accuracy requirements, and performance conditions. The April 2026 release expanded testing to include newer large language models and reasoning workloads. Test suites that keep adding newer models reflect how fast things move, which is why we look back over the past year in our AI chips market report.
Even these tests require careful reading. Results can depend on the number of accelerators, software optimizations, batch sizes, model precision, and latency constraints.
Consider two services running the same language model. One serves a single user who expects an immediate response. The other processes thousands of requests in batches. Hardware optimized for maximum throughput may perform very differently from hardware optimized for low latency.
Vendor benchmarks introduce another complication because companies naturally highlight workloads that favor their own processors.
Cerebras' reported speed advantage for GPT-5.6 Sol is useful evidence of a real capability. AMD's published performance comparisons also help identify promising workloads. Neither establishes an across-the-board advantage over Nvidia.
What we still lack is a broad, independently verified dataset comparing the complete operating costs of Nvidia, AMD, Google TPU, Amazon Trainium, Cerebras, and other systems under identical production conditions.
That limits how precisely we can rank their economics. It doesn't change the fact that multiple architectures are already commercially viable.
Will AI inference move away from Nvidia faster than AI training?
AI inference looks more suitable for specialized hardware than frontier-model training, especially when companies run the same models repeatedly at enormous scale.
Meta's deployments illustrate the difference. The company has already installed hundreds of thousands of custom MTIA accelerators, largely for recommendation and advertising inference. Its newer generations are extending that specialization into generative AI.
Anthropic provides another example, using both Amazon Trainium and Google TPUs for major AI workloads. Cerebras has found a role in fast frontier-model serving, where extremely low response times create different hardware priorities. Workloads split across Trainium, TPUs and Cerebras make the likely future winners harder to call, and we weigh them in our AI chips report.
Training is also moving beyond Nvidia, so the distinction is not absolute. But training leading models often involves rapidly changing architectures, enormous distributed systems, and demanding communication between processors. A flexible platform can be particularly valuable when researchers are testing new techniques.
Inference provides more opportunities to optimize a stable model over a long period. The larger the request volume, the more attractive that investment becomes.
Our expectation is that inference will fragment across competing hardware architectures faster than frontier-model training. The commercial incentives are simply stronger for repetitive, predictable workloads.
Still, we cannot calculate how quickly Nvidia's inference market share is changing from the available public data. Training and inference spending are not consistently separated across major providers, and long-term commitments do not equal deployed capacity. Claims that most inference has already moved away from Nvidia would be premature.

This is a preview page. Spotted an outdated number? That’s normal here. The report you get is always the freshest version.
Could cheaper AI inference actually help Nvidia sell more GPUs?
Cheaper inference could support continued growth in Nvidia's GPU business because lower costs allow companies to serve more requests and build more demanding AI applications.
The arithmetic is straightforward. If the number of tokens generated doubles while the computing cost per token falls by 40%, total spending on that workload would still rise by 20%, assuming the same cost structure.
This is an illustrative scenario, but it explains how improvements in efficiency can coexist with rising hardware demand.
Nvidia's recent results fit that broader possibility. As seen above, quarterly data-center revenue grew 117% year over year despite the expansion of competing inference processors.
However, growing revenue does not guarantee that Nvidia will maintain its current profitability. Its reported 75% gross margin gives competitors a strong incentive to develop cheaper alternatives, particularly for large, repetitive workloads.
There are three different outcomes worth separating. Nvidia could lose inference market share while still increasing revenue. It could face pricing pressure even as demand rises. Or, in a more severe scenario, improvements in competing hardware could eventually reduce the amount customers need to spend on Nvidia systems.
Today, the evidence points to growing competition alongside exceptionally strong Nvidia sales. A sustained decline in Nvidia's pricing power has yet to be demonstrated.
When should a company choose Nvidia GPUs for AI inference?
Nvidia is still a strong default for businesses that need to run different AI models reliably, while competing processors deserve serious consideration when cost, speed, or workload specialization matters more.
For example, a startup frequently switching between open-weight models may benefit from Nvidia's CUDA ecosystem. A large cloud operator serving billions of similar requests could save money by optimizing custom hardware. An application that needs extremely fast interactive responses may find Cerebras attractive, while a mobile application running a compact model locally may require no data-center accelerator.
The right choice depends on the application and the costs measured in production.
| AI inference workload | Hardware to consider | Main reason |
|---|---|---|
| Frontier AI model serving | Nvidia, Google TPU, AWS Trainium, AMD | Scale and software compatibility |
| High-volume chatbot | Nvidia, TPU, Trainium, AMD | Cost per token and throughput |
| Ultra-fast coding assistant | Cerebras, Nvidia, specialized processors | Low response latency |
| Advertising recommendations | Meta MTIA, custom ASICs, GPUs | Efficiency across repeated predictions |
| Enterprise open-weight models | Nvidia, AMD | Deployment flexibility |
| Long-context document analysis | High-memory GPUs, TPUs, custom accelerators | Memory capacity and bandwidth |
| Smartphone AI assistant | Apple Silicon, mobile NPUs | Local processing and energy efficiency |
| Offline small-model inference | CPUs, integrated GPUs, NPUs | Existing hardware and low operating costs |
| Frequently changing AI models | Nvidia, AMD | Broad framework support |
| Large-scale custom AI services | TPUs, Trainium, proprietary ASICs, GPUs | Long-term cost optimization |
A company evaluating inference hardware should test its actual models at realistic request volumes, with the latency and quality requirements customers expect. An impressive hardware benchmark can easily become irrelevant once engineering costs, utilization, and operational reliability are included.
Do you still need Nvidia GPUs for AI inference?
No. Nvidia GPUs are no longer necessary for AI inference, and that conclusion is supported by major commercial deployments rather than experimental benchmarks alone.
Google serves frontier AI workloads on TPUs. Anthropic uses more than one million Amazon Trainium2 chips for training and inference. Meta operates hundreds of thousands of proprietary accelerators. OpenAI has demonstrated GPT-5.6 Sol running on Cerebras at up to 750 output tokens per second.
Taken together, these deployments show that the alternatives now cover frontier language models, recommendation systems, fast interactive applications, and large-scale cloud services.
Nvidia still has enormous commercial advantages. Its CUDA ecosystem remains widely supported, its hardware can serve many different workloads, and its latest reported data-center revenue reached $89 billion in a single quarter. Customers continue buying Nvidia infrastructure even as competing processors become more capable.
Businesses with stable, high-volume workloads can increasingly choose processors optimized for their needs, while companies requiring flexibility may continue to prefer Nvidia.
We expect AI inference to rely on a wider combination of GPUs, custom accelerators, CPUs, and specialized processors. The shift is already happening, although there is not enough transparent market-share data to determine exactly how much inference spending Nvidia has lost.
Nvidia remains one of the strongest suppliers in AI computing. But its GPUs are no longer indispensable, and the next stage of competition will increasingly come down to which hardware can serve a specific model at the lowest real cost.
Our methodology
This analysis evaluates whether Nvidia GPUs remain necessary for AI inference by examining five dimensions: commercial adoption, technical capability, inference economics, software ecosystems, and competitive momentum. We compare operating deployments, infrastructure commitments, processor capabilities, independent benchmarks, and financial disclosures to understand how far alternative architectures have progressed.
We prioritize observable deployments over announced plans. Processors already serving production workloads are treated differently from future capacity agreements, and measured performance is distinguished from vendor efficiency targets. For example, Anthropic's deployment of more than one million Trainium2 chips provides evidence of operational adoption, while multi-gigawatt infrastructure commitments primarily indicate future capacity plans.
To assess Nvidia's commercial position, we use its fiscal second-quarter 2027 financial results and regulatory disclosures. We compare data-center revenue growth with the expansion of competing architectures, but do not treat total data-center revenue as a direct measure of inference market share. Nvidia does not separately disclose enough training and inference revenue to establish a precise market-share trend.
For competing hardware, we examine Google's TPU deployments, Amazon's Trainium infrastructure, Meta's MTIA processors, Microsoft's Maia roadmap, AMD's Instinct accelerators, Apple's local inference framework, and specialized Cerebras and Groq systems. Each is evaluated according to documented production usage, software compatibility, performance characteristics, and deployment maturity.
Our performance comparisons distinguish output-token speed, overall throughput, latency, memory requirements, and cost efficiency. Vendor demonstrations establish capabilities under specific conditions, while MLCommons' MLPerf Inference results provide a more standardized technical reference. We do not interpret a single benchmark result or advertised speed advantage as proof of lower total inference costs across every workload.
For inference economics, we consider accelerator pricing, generated tokens, utilization, workload characteristics, memory, infrastructure overhead, and engineering requirements. The cost-per-token example in the article is hypothetical and illustrates why hourly hardware prices cannot establish which architecture is cheaper in production.
We also examine how inference architecture is changing, particularly the separation of prompt prefill and token decoding across different processors. We use documented collaboration announcements and technical frameworks to distinguish working systems from proposed configurations, without assuming that every announced architecture has already reached commercial scale.
Key financial and commercial sources include Nvidia's fiscal Q2 2027 results, Nvidia's SEC filing, Amazon's fourth-quarter 2025 results, Anthropic's expanded Amazon collaboration, Anthropic's Google TPU expansion, and Broadcom's regulatory disclosure on TPU capacity.
For proprietary hardware and alternative architectures, we use Google's Ironwood announcement, Meta's MTIA deployment announcement, Microsoft's Maia roadmap, AMD's Instinct MI350 documentation, and Apple's Foundation Models framework presentation.
For specialized inference, serving architectures, and independent performance evaluation, we refer to OpenAI's GPT-5.6 Sol Ultrafast preview, OpenAI's GPT-5.3-Codex-Spark announcement, Groq's Nvidia licensing agreement, Cerebras' AWS collaboration, Nvidia's Dynamo documentation, MLCommons' MLPerf Inference v6.0 results, and Nvidia's technical research on disaggregated inference.
Our conclusions combine evidence of real-world deployment, measurable technical capability, commercial performance, and operational limitations. The central distinction is between proving that Nvidia alternatives are commercially viable and proving that they consistently outperform Nvidia economically. The available evidence supports the first conclusion much more strongly than the second.
Written by the New Market Pitch teamWe track new markets so founders and investors can move faster. About us